BM25 Part 3: Benchmarking Python BM25 Libraries
Benchmarking BM25 implementations: bm25-sparse, rankbm25, numpy vectorization, scipy, and plain Python. Find the fastest BM25 for your search use case.
مقالات وتجارب وملاحظات حول نماذج التضمين.
Benchmarking BM25 implementations: bm25-sparse, rankbm25, numpy vectorization, scipy, and plain Python. Find the fastest BM25 for your search use case.
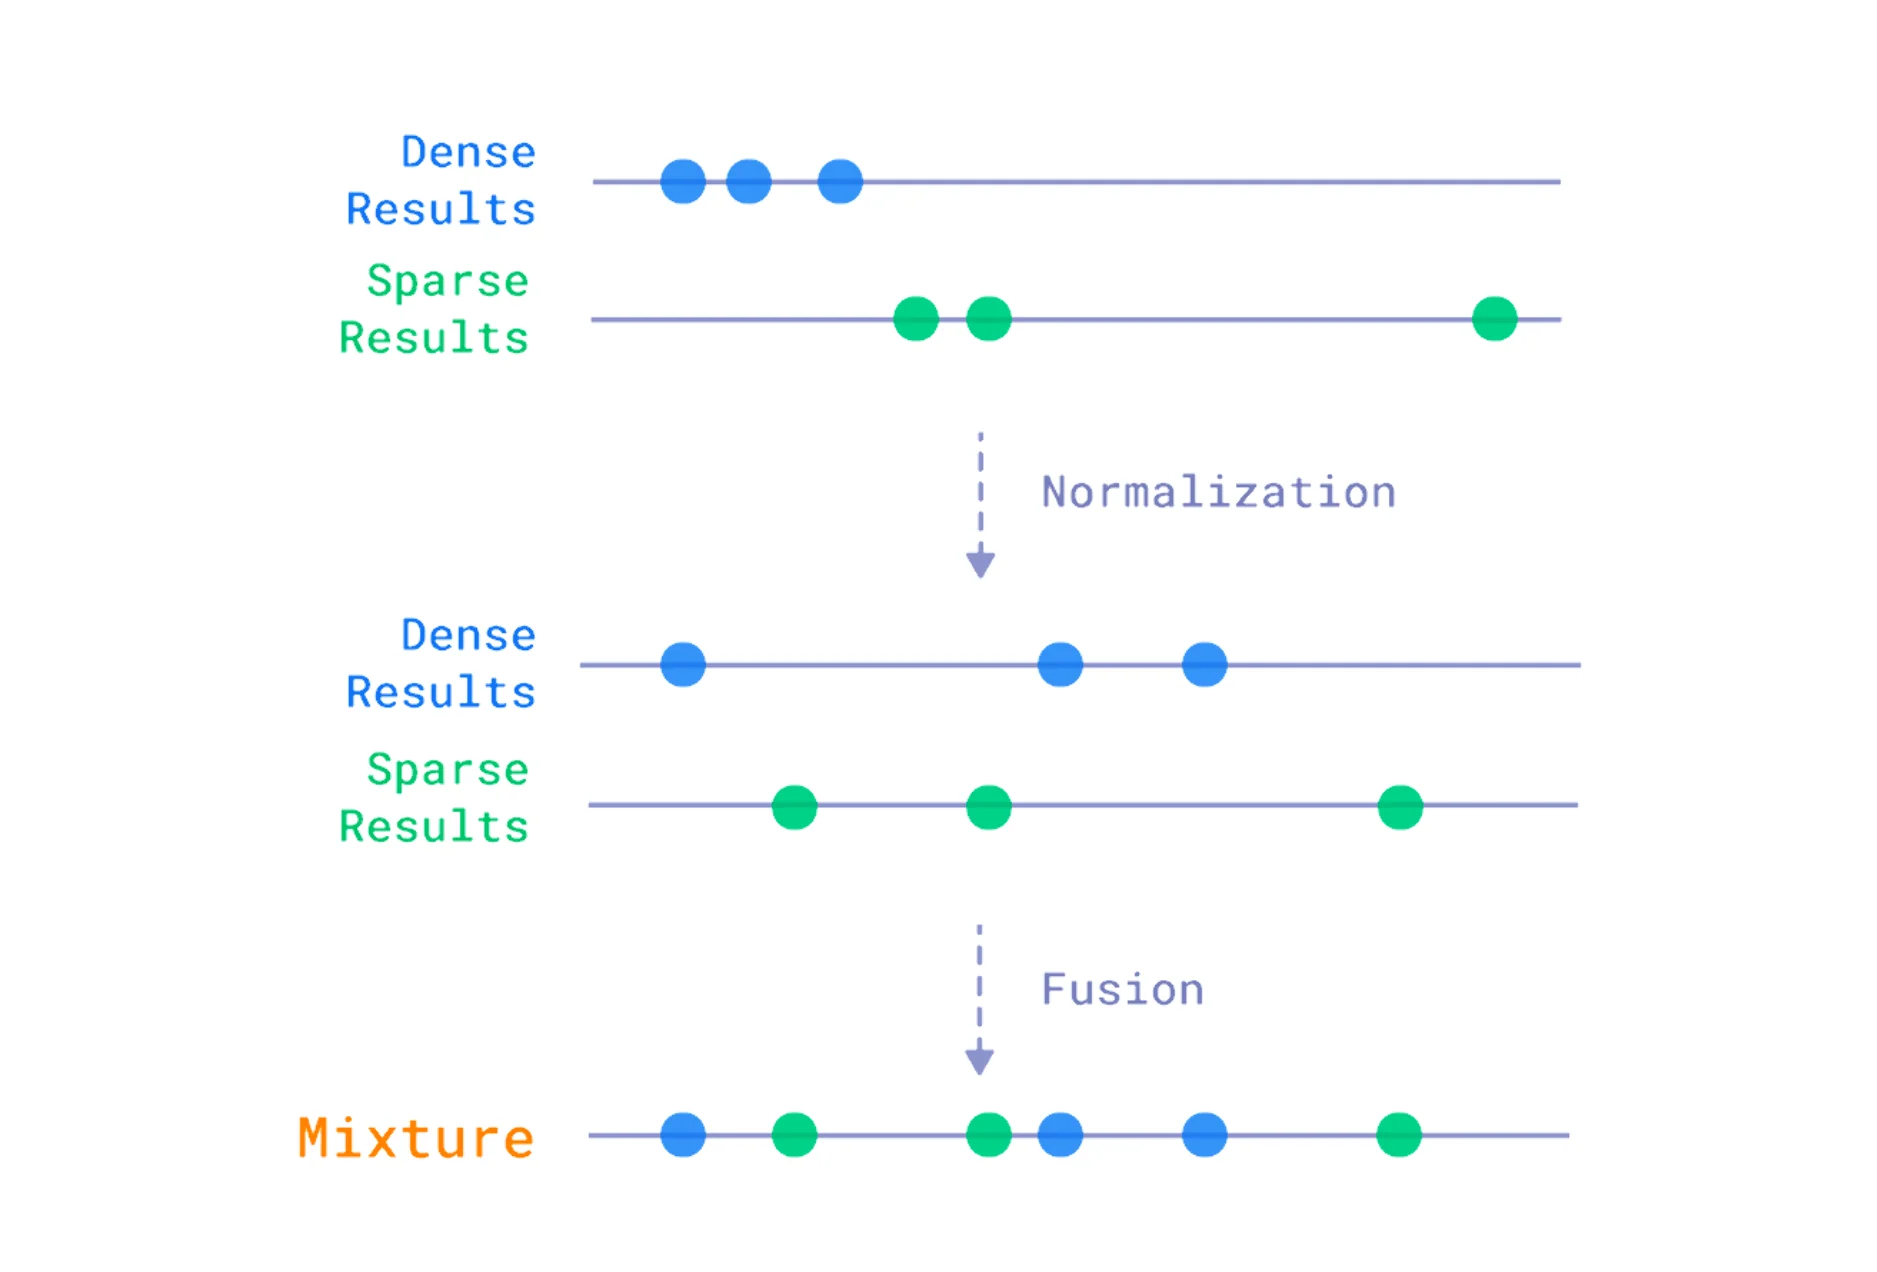
Step-by-step guide to building a bilingual hybrid search system using Qdrant and BM25. Learn how to optimize real estate search with n-grams and RRF fusion.
Learn how BM25 improves search relevance over TF-IDF. This guide covers the math and Python code for implementing BM25 ranking from scratch with clear examples.
Learn how to diversify search results in a RAG system using Qdrant and Pyversity. Covers MMR, DPP, and other diversity algorithms with practical Python examples.
Analyze Bojji and Zarra model2vec embeddings for Arabic, compare MTEB average score with all-MiniLM-L6-v2 and other static models.
Explore Late Interaction models like ColBERT and ColPali for efficient token-level semantic search balancing speed and accuracy.
Overview of MTEB, covering 58 datasets across 8 tasks, benchmarking models and explaining the nDCG@10 retrieval metric.
tiny-gte is a 45MB distilled transformer from gte-small that produces 384D embeddings for efficient semantic search and vector DBs.