Embedding Models, Vector Databases & Semantic Search
This is a curated collection of my writing on text embeddings, sparse retrieval, vector databases, and semantic search architecture.
If you’re building search systems or RAG pipelines, start here.
I’ve spent the last couple of years deep in the embedding world — training tiny Arabic models, implementing BM25 from scratch, and building hybrid search that actually works for Arabic text. This series covers both theory and code, from sparse embeddings to dense retrieval and everything in between.
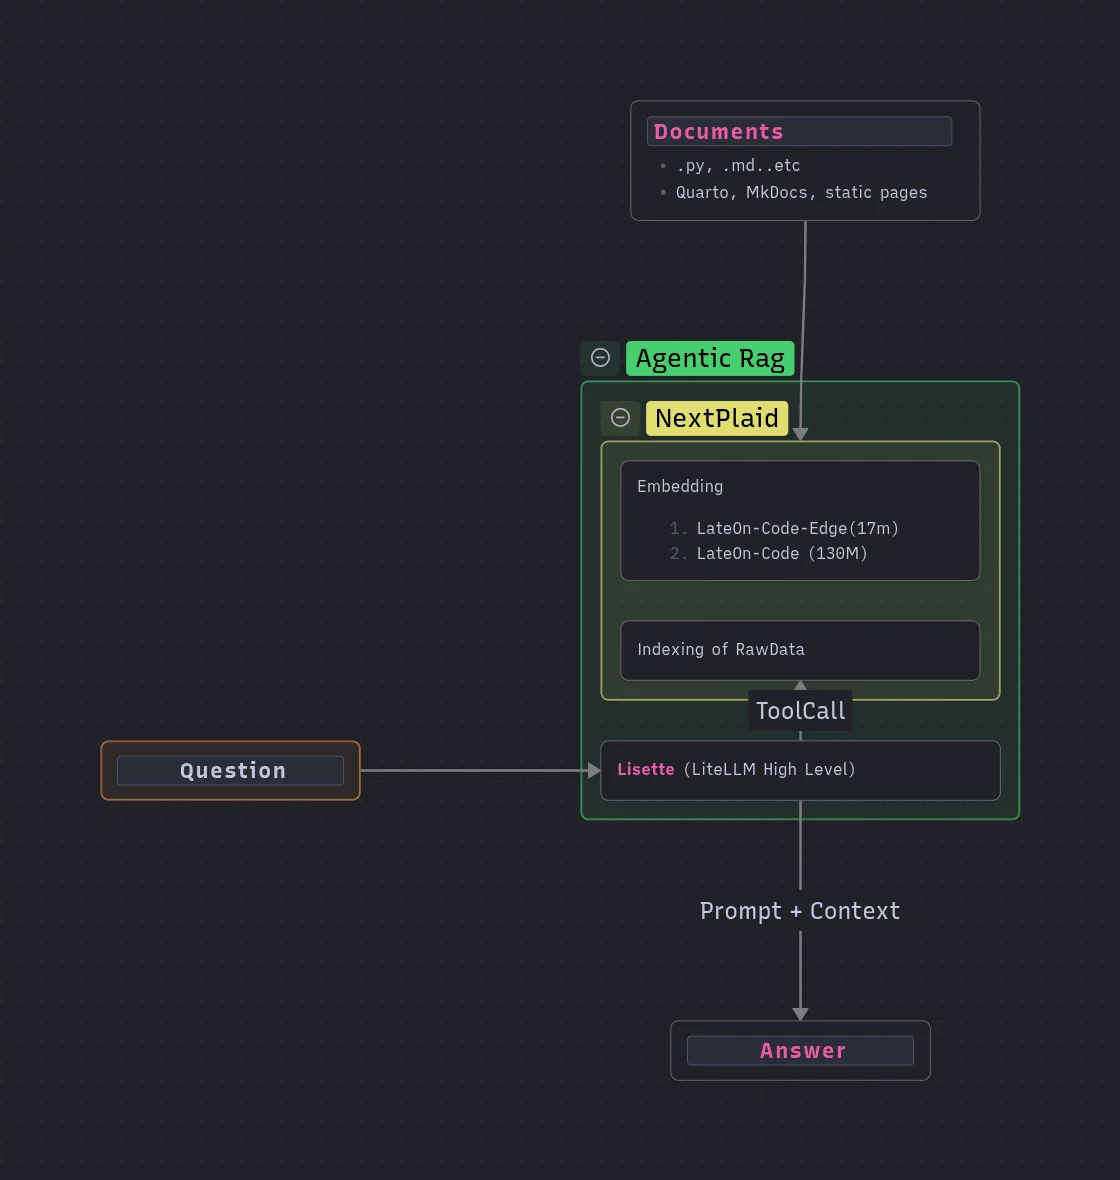
- HyperRun — A self-hosted AI docs widget with semantic code search
- HyperRun + FastHTML — Streaming chat architecture with HTMX and SSE
- Late Interaction — ColBERT and multi-vector retrieval explained
- BM25 from Scratch — Implementing classical sparse retrieval
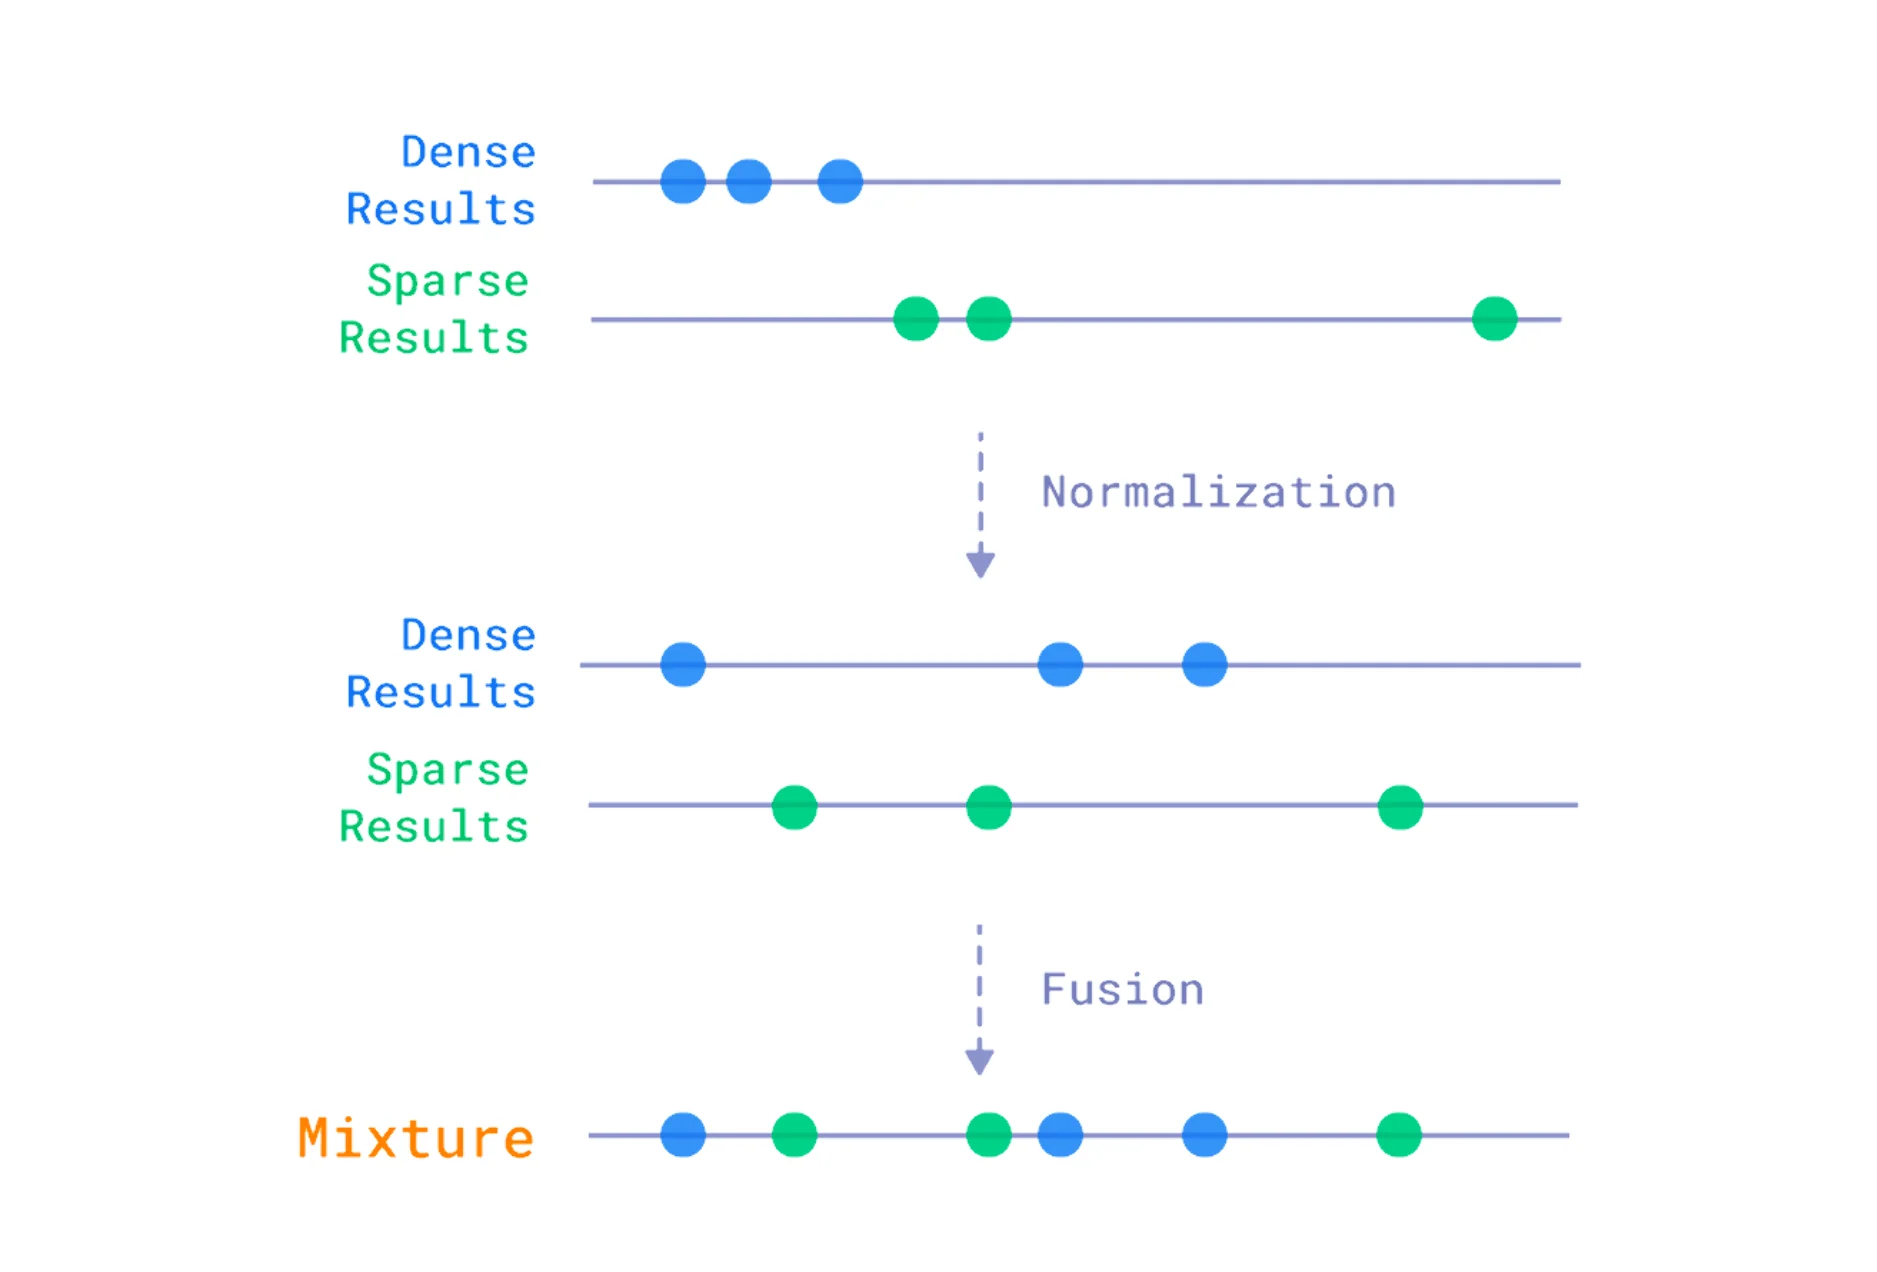
- BM25 + Qdrant for Arabic — Practical sparse+dense hybrid search
- BM25 Benchmarks — Full comparison across datasets
- Vector Database Book — Notes on building vector search systems
Each article builds on the last — start with BM25 if you’re new, then move to late interaction and HyperRun once you’ve got the foundations down.